RAPID-AI has seven principles, five workflow stages, and multiple maturity levels. Those components are useful because they give L&D teams a practical way to structure AI-assisted instructional design. But underneath the framework sits one operating rule that needs to remain visible across all of them:
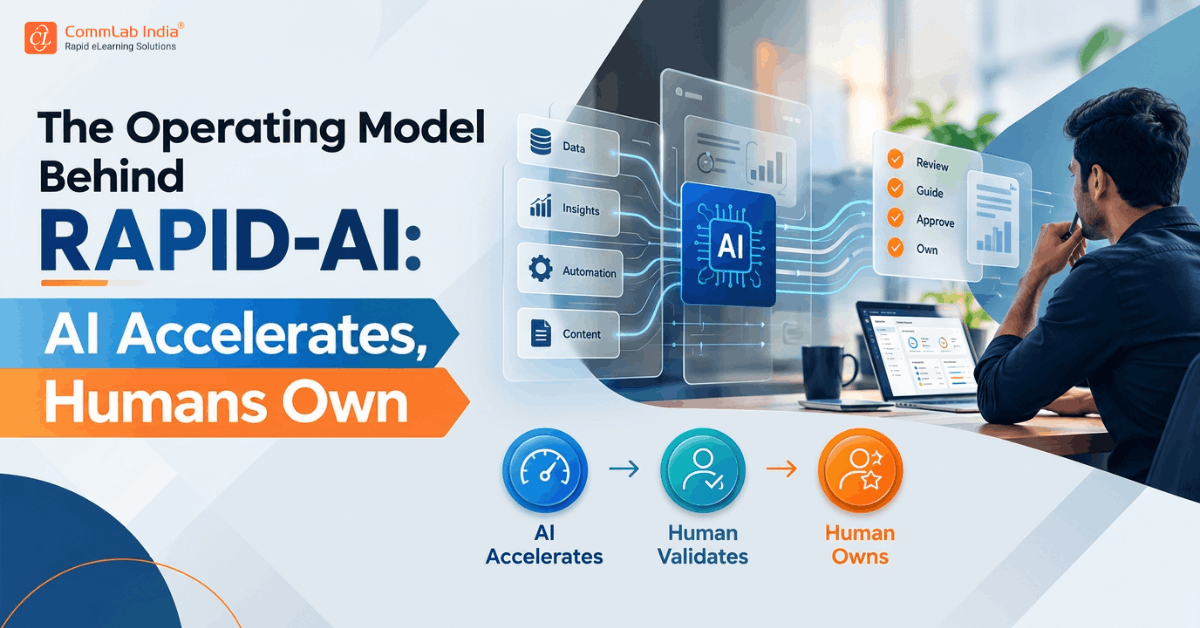
AI accelerates. Humans own.
AI can speed up drafting, option generation, summarization, analysis, and early review. Humans remain responsible for why the learning exists, whether the approach fits the audience and context, and whether the finished experience is accurate, instructionally sound, and ready to release.
The distinction is easy to agree with when a project is progressing normally. It becomes more difficult when the deadline is tight, the AI-generated draft looks polished, and the team is under pressure to move faster. That is when the operating model matters most, because it gives the team a simple rule for deciding whether AI is merely accelerating the work or beginning to replace a decision that still requires human judgment.
Why the Model Matters Most Under Deadline Pressure
Under normal conditions, most L&D teams are unlikely to argue that AI should independently own instructional decisions. The risk usually appears in smaller, more practical ways. A storyboard looks finished enough, so the team shortens the review. An assessment generated from approved source material seems reasonable, so no one checks whether it truly measures the objective. A launch date moves forward, and a checkpoint that normally happens before production is treated as optional.
None of these decisions may appear serious in isolation. Over time, however, they change how the team actually works. A process that originally used AI to accelerate drafting can gradually begin allowing AI-generated output to pass through decisions that were intended to remain human-owned.
That is why the phrase AI accelerates, humans own needs to function as more than a statement of values. It should act as a practical decision rule. When a shortcut is proposed, the team should be able to ask whether the change simply speeds up the work or whether it removes a judgment point that still belongs to a qualified person.
What “AI Accelerates” Actually Means
The acceleration side of the model covers a wide range of useful applications. AI can help instructional designers draft first versions, generate multiple approaches, summarize raw SME material, organize complex information, produce scenario or assessment options, and flag possible gaps or inconsistencies for review.
These uses create value because they reduce the time required to reach a point where a human can evaluate, compare, refine, or approve the output. In other words, AI is helping the team move faster through a task that would otherwise take longer.
That does not mean the output should automatically become the final decision.
Consider a product-training scenario. AI may generate three possible structures in minutes. One may focus on a customer objection, another on a product comparison, and a third on a troubleshooting situation. The designer can review those options and decide which one best reflects the learner’s job, the business context, and the intended performance outcome. This is where using AI as a thinking partner is more useful than treating it as a content machine.
The efficiency comes from generating the options quickly. The instructional decision remains human.
What “Humans Own” Actually Means
Human ownership applies most strongly to the parts of instructional design that depend on context, consequences, and accountability. Three areas are particularly important: intent, judgment, and quality.
- Intent: Intent refers to why the training exists and what performance problem it is intended to address. AI can help organize evidence or summarize source material, but it cannot own the business decision about what behavior needs to change.
- Judgment: Judgment involves choosing the approach that fits the audience, work environment, risk level, and constraints. AI can suggest alternatives, but it cannot be accountable for selecting the one that is appropriate for a specific organization and learner population.
- Quality: Quality is the final determination that the learning experience is accurate, relevant, instructionally sound, and suitable for release. That requires looking beyond whether the content reads well. In L&D, a polished course can still fail if it addresses the wrong performance need, uses unrealistic scenarios, or assesses recall when learners need to demonstrate application.
These ownership points appear throughout RAPID-AI. They are present in performance-gap diagnosis, approach selection, SME validation, assessment review, and final sign-off. The five-stage AI-assisted instructional design workflow gives those decisions a practical sequence.
Why Teams Need to State the Rule Explicitly
If the principle seems intuitive, it is reasonable to ask why it needs to be written down at all. The answer is that informal rules are often most vulnerable when pressure increases.
A team may skip a review once because the deadline is unusually tight. Nothing goes wrong. The next time a similar situation appears, skipping the same step feels less risky because the previous exception did not cause a visible problem. After several projects, the checkpoint may still exist in the documented workflow, but it no longer functions as a reliable part of the process.
No one has formally decided to remove it. The practice has simply changed through repetition.
An explicit operating model helps interrupt that drift. Instead of relying on a vague reminder to “use AI responsibly,” the team can ask more useful questions: Is AI accelerating this step, or are we allowing an AI-generated output to replace a human decision? Which ownership point disappears if we skip this review? Who remains accountable for the result? These questions are easier to act on when AI governance is embedded in the team’s workflow.
A Practical Example: A Compliance Deadline Moves Forward
Consider an illustrative situation. A compliance module that normally has three weeks for development suddenly needs to launch in three days.
AI helps the team move quickly. It organizes the source material, drafts portions of the module, and generates assessment items. The SME reviews the content and confirms that it is factually accurate. Visually and editorially, the module looks finished.
The remaining step is an instructional review of objective-assessment alignment.
Under deadline pressure, that checkpoint may start to look expendable. The content is accurate, the questions seem reasonable, and everyone wants to meet the launch date. It may feel efficient to move forward.
The operating model clarifies the issue. AI has already done what it is supposed to do: accelerate the work. The human ownership point on instructional alignment still needs to happen.
If the learning objective expects employees to apply a compliance decision in context, the assessment cannot be accepted simply because the questions are grammatically correct and factually accurate. Someone still needs to confirm that the assessment measures the intended behavior.
Compressed timelines make that review more important, not less, because there is less room to discover a weak instructional decision later.
The Model Should Work as a Decision Rule
One of the easiest mistakes is treating AI accelerates, humans own as a statement that appears in a kickoff deck and is then forgotten.
A useful operating principle should help teams make decisions in real moments of pressure. When someone proposes skipping a review, accepting an AI-generated recommendation without further evaluation, or compressing a human approval step because the project is late, the principle should help clarify whether ownership is being transferred.
If the shortcut changes who makes the decision, the issue is no longer only about speed. It has become a governance decision.
This is where the model becomes practical. It helps teams separate legitimate acceleration from shortcuts that weaken accountability.
Apply the Model Consistently Across Projects
Another failure mode is selective enforcement. A high-profile leadership program may receive careful review, while a smaller internal module moves through with fewer checks because fewer stakeholders are watching it.
Not every project needs identical review intensity. RAPID-AI already allows oversight to adapt to practitioner maturity, risk, and context. However, the ownership principle itself should remain stable.
If a decision requires human judgment in one project, reducing the project’s visibility does not automatically make that judgment unnecessary. The relevant question is whether the nature of the decision has changed.
A low-profile project can still contain poor assessment alignment, inaccurate source interpretation, or an inappropriate learning treatment. The level of oversight may vary, but the human-owned decision still needs to be made.
How Leaders Reinforce the Model Day to Day
The operating model is shaped as much by ordinary management decisions as by formal governance documents.
A team member asks whether a review can be skipped because the schedule has moved. A manager needs to decide whether to approve the shortcut. That response teaches the team more than a policy statement because it shows which rules actually hold when the work becomes difficult.
If leaders repeatedly waive human ownership points whenever timelines become uncomfortable, the team learns that those checkpoints are negotiable. Over time, the exception becomes the working norm.
Consistency does not mean ignoring genuine business pressure. A leader can acknowledge that the deadline is real while still protecting the ownership point. The team may shorten the review meeting, narrow its scope, bring in another qualified reviewer, or adjust what can realistically be delivered by the deadline.
The important distinction is that the capacity problem is solved without quietly transferring a human decision to AI.
Make Human Judgment Visible
Teams are more likely to respect human review when they can see what it catches.
Suppose AI generates a set of assessment questions that appear strong. During review, an instructional designer notices that all of the questions test recognition, even though the learning objective requires learners to apply a procedure in a realistic situation.
That is worth discussing with the team.
The lesson is not that AI failed. The lesson is that the workflow worked as intended. AI accelerated the production of a usable first draft, and human judgment identified an instructional weakness before the course was released.
Examples like this make the ownership side of the model tangible. They also help prevent review from being seen only as a delay in an otherwise efficient process.
Measure Whether the Model Holds Under Pressure
If the operating principle matters most when timelines become difficult, that is where teams should look for evidence that it is working.
One practical measure is checkpoint completion on compressed-timeline projects. For each project, the team can record whether the required human ownership points were completed as documented.
The purpose is not to create a punitive audit. It is to understand whether behavior changes when pressure increases.
For example, if required checkpoints are consistently completed on normal projects but drop noticeably on fast-turnaround work, leaders have a useful signal. The organization may agree with the principle in theory while behaving differently under the exact conditions where it is supposed to matter most. This kind of evidence complements a broader approach to evaluating AI use in instructional design teams.
That is more informative than asking whether employees believe in responsible AI use. Belief and behavior are not the same thing.
Watch for Gradual Erosion, Not Only Major Failures
Governance usually weakens through a series of small changes rather than one dramatic decision. A review is skipped once, then again. Later, the team begins planning projects as though that review is optional.
Tracking behavior over time can reveal this drift before it becomes embedded.
A gradual decline in checkpoint completion on compressed projects can help leaders diagnose what is happening. The issue may be insufficient review capacity, unrealistic delivery expectations, unclear ownership, weak escalation paths, or a governance requirement that no longer fits the work.
The point of measurement is to identify the operating problem early enough to correct it.
Avoid Turning the Measure Into an Individual Scorecard
Checkpoint tracking is most useful when it evaluates the system rather than becoming a mechanism for individual blame.
If employees believe every missed checkpoint will be used against them in a performance review, they have an incentive to hide deviations rather than surface them. That makes the data less reliable and makes governance failures harder to correct.
A skipped checkpoint may reflect a wider problem, such as insufficient reviewer availability, conflicting management instructions, unrealistic deadlines, or an unclear exception process.
Individual accountability still matters, but it should not obscure structural weaknesses in the operating environment.
Why This Matters Specifically in L&D
The principle can apply to many professional contexts where AI accelerates work that still requires domain expertise. L&D has a particular challenge because instructional quality is not defined by polished language alone.
A learning asset can be clear, well organized, and visually strong while still failing to support meaningful performance.
The more important questions are whether it addresses the right performance need, fits the audience and context, gives learners appropriate practice, measures the intended capability, and remains accurate enough for the environment in which it will be used.
AI can support the analysis behind those questions, generate alternatives, and flag possible weaknesses. It cannot carry accountability for the final answer. This is also why prompting method matters less than the larger instructional design method when teams scale GenAI use.
That is why human ownership remains necessary even as AI becomes better at producing content that looks finished.
Frequently Asked Questions
What is the core operating principle behind the RAPID-AI framework?
The principle is AI accelerates, humans own. AI can speed up drafting, analysis, option generation, and review support. Humans remain responsible for intent, judgment, and final quality.
Why does this principle matter more under deadline pressure?
Tight deadlines make polished AI output easier to accept without completing the normal review. The operating model helps teams distinguish between legitimate acceleration and the removal of a human-owned decision.
How can teams keep the operating model from eroding?
Use it as a standing decision rule, especially when shortcuts are proposed. Teams should also monitor whether required human ownership points are completed consistently across different project conditions.
What role do managers play?
Managers reinforce the model through everyday decisions. Their response when someone asks to skip a checkpoint under pressure determines whether governance is experienced as a real operating rule or an optional principle.
Should checkpoint completion be tied to individual performance reviews?
Usually not. It is more useful as a system-level diagnostic that shows whether the workflow holds under pressure and where capacity or governance problems may exist.
Conclusion
The practical value of AI accelerates, humans own is that it gives L&D teams a simple way to distinguish between speed and responsibility.
AI should create leverage where it is strongest: generating options, organizing information, drafting content, and helping teams surface possible issues earlier. Human expertise remains responsible for the decisions that determine whether the learning is relevant, accurate, instructionally sound, and fit for release.
The model is working when that distinction survives the difficult projects, not only the easy ones. That is the real test of whether AI has become part of a scalable instructional system rather than simply a faster way to produce content.